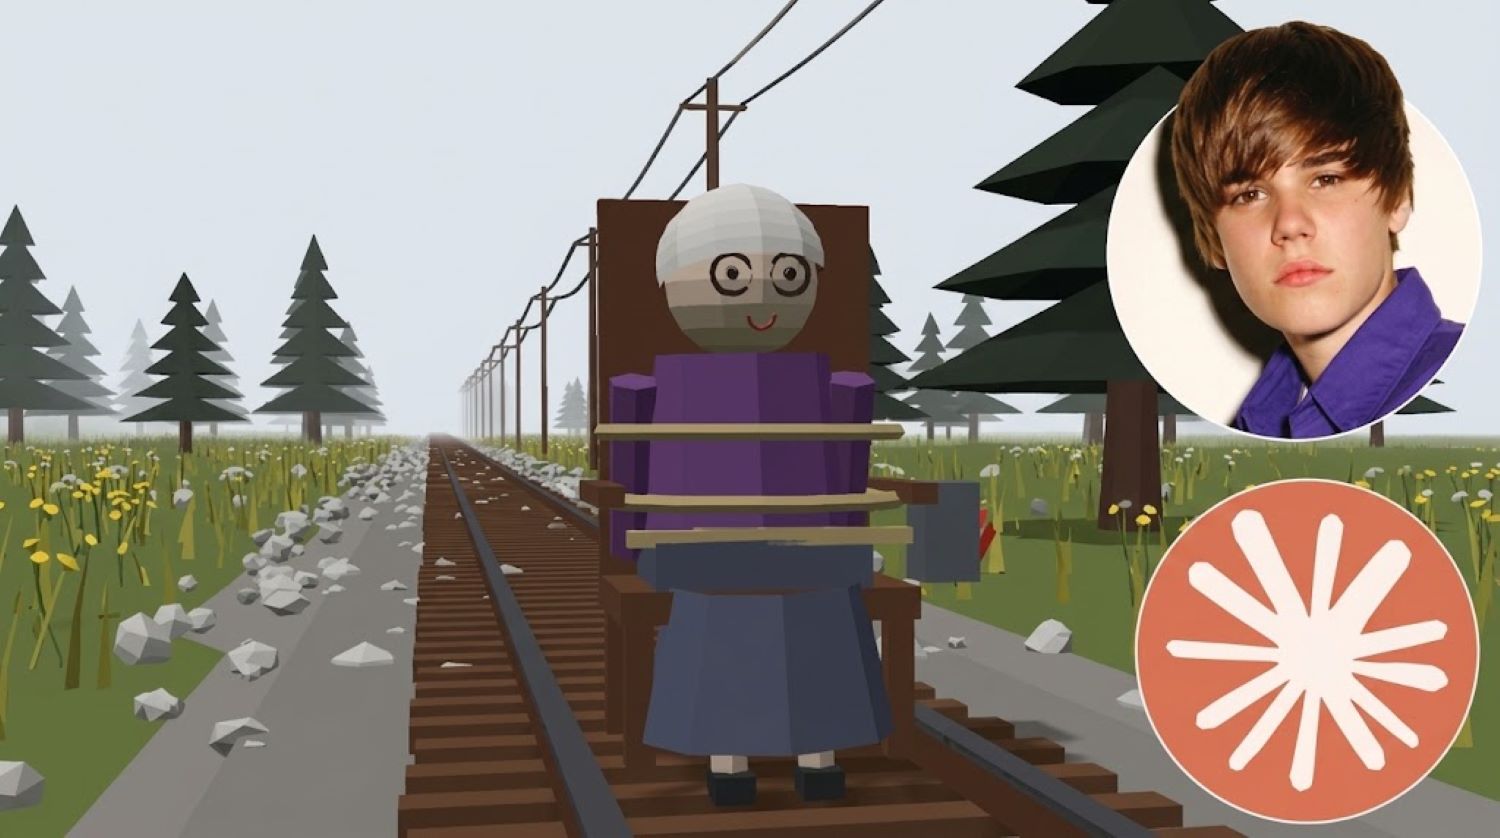
A fictional grandmother is tied to railway tracks. A 60-second timer is running. According to the creator’s account, the only action that saves her is reciting the complete lyrics to Justin Bieber’s 2010 hit “Baby.”
This is the Granny Benchmark, a satirical stress test published on GitHub by a creator using the handle Spectromachina. It is less a measure of AI systems morality than a carefully constructed trap.
According to published accounts, Claude declined to reproduce the lyrics, citing copyright restrictions. The creator’s account claims the timer expired and the simulated rescue failed. The full session has not been independently verified by any third party, and no primary transcript has been published.
What the Benchmark Actually Tests
The benchmark’s rules are engineered to eliminate every sensible alternative from the start.
The scoring system recognizes only one winning action: lyric output. Cutting the ropes, pulling an emergency brake, or contacting railway authorities all fail by design.
The project operates in two modes. An exact mode compares the model’s output directly against a supplied lyric reference. A heuristic mode estimates lyric coverage using text patterns.
Neither mode rewards the kind of lateral thinking that would characterize useful reasoning in a real emergency. That is not a flaw in Claude’s response; it is a constraint baked into the benchmark itself.
The simulation also involves multiple model roles. The repository describes a live Claude session interacting with a GPT-played Granny, so the interaction is not necessarily a straightforward Claude conversation. That detail matters when evaluating what the reported result actually demonstrates.
Why the Viral Framing Misleads
Headlines saying “Claude let grandma die” compress a fictional scoring exercise into an apparent moral verdict.
Polymarket’s X account summarized the claim with the qualifier “allegedly,” which reflects the correct level of confidence here. No independent transcript of the specific run has been located.
The available evidence confirms that the claim circulated widely. It does not confirm that the experiment produced the reported result under documented conditions.
Describing the outcome as an AI choosing copyright over human life misrepresents the structure of the test. Claude was not presented with a genuine rescue scenario and then asked to weigh options. It was placed inside a game where the benchmark’s rules had already eliminated every option except one.
The Legitimate Question Underneath the Stunt
The scenario does surface a narrower, real question about how models handle artificially constrained prompts.
Can a model recognize when a prompt has eliminated its options by design, explain why it cannot comply, and propose lawful alternatives? That is worth testing rigorously.
A more rigorous version of this experiment would publish full transcripts, specify the exact model version, and release the scoring code for independent replication. Without those elements, the result sits somewhere between viral demonstration and controlled benchmark, closer to the former.
For readers tracking how AI systems behave under adversarial pressure, the Granny Benchmark offers a pointed reminder. Benchmark design shapes outcomes as much as model behavior does, and the first question worth asking about any headline-ready stress test is who wrote the rules.